Multimodal Search · MLLM Representation · Video Understanding
Zhicheng Wang 王志诚
I build large-scale multimodal systems for real-world search and question answering, with a focus on MLLM-based embeddings, Video LLMs, and scalable representation learning.
I am currently an Algorithm Researcher at ByteDance, where I work on general-purpose image search and question-answering systems on Douyin, as well as foundational technologies for general video understanding. My research focuses on MLLM-based embedding models, Video LLMs, and scalable multi-modal representation learning. Before joining ByteDance, I was a research intern at Alibaba Pailitao, one of the largest e-commerce visual search scenarios in China, where I explored large-scale post-training methods for MLLM-based representations in industrial search systems. I received both my Master’s and Bachelor’s degrees from Huazhong University of Science and Technology, supervised by Prof. Zhiguo Cao. I am always open to collaborations on multimodal retrieval, representation learning, open-world localization and counting, and video-language understanding.
News
- 2026.08 Released DME Technical Report, an efficient and powerful MLLM embedding model that achieves SOTA performance on the MMEBv2 leaderboard. See also our Tech Blog.
- 2026.02 Released Pailitao-VL, a unified embedding and reranker for real-time multi-modal industrial search.
- 2025.11 Released PDF-VLM2Vec, an efficient training framework for MLLM embedding models.
- 2025.11 IPFormer-VideoLLM was accepted to AAAI 2026.
- 2025.07 SRefiner was accepted to ICCV 2025 and selected as a Highlight.
- 2025.06 Released IPFormer-VideoLLM, a Video LLM designed for multi-scene video understanding.
- 2025.04 DAM was accepted to Pattern Recognition.
- 2025.03 CAD-GD was accepted to CVPR 2025.
- 2023.12 CACViT was accepted to AAAI 2024.
Publications
(* denotes corresponding author.)
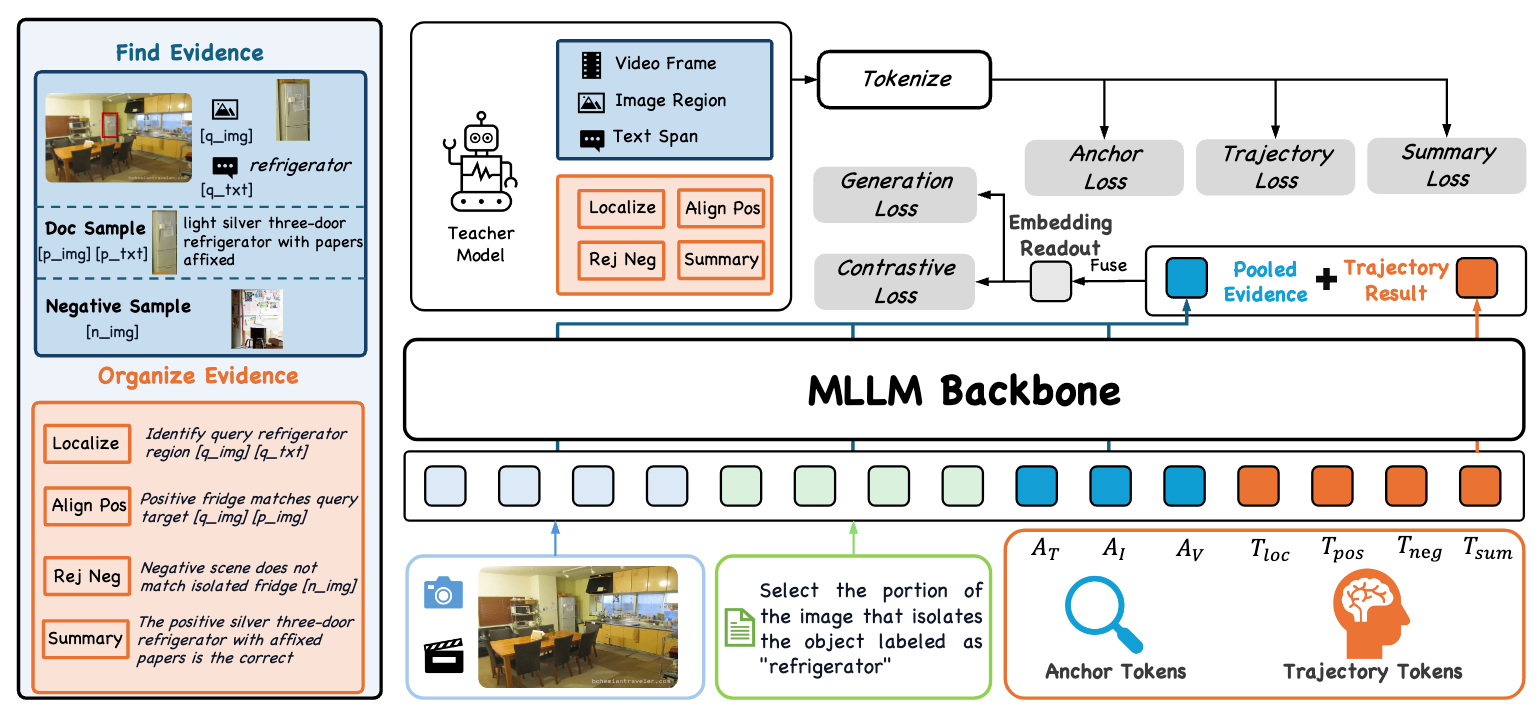
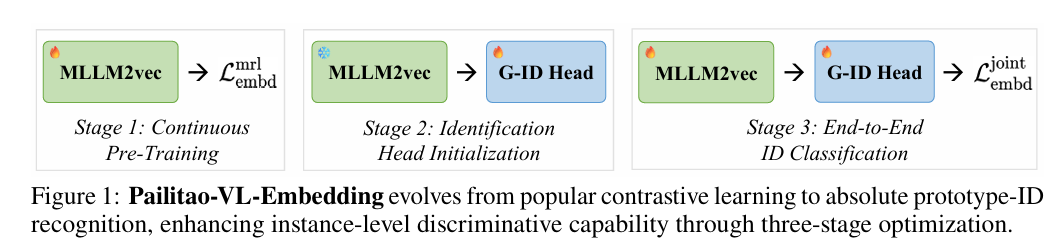
Tech Report Pailitao-VL: Unified Embedding and Reranker for Real-Time Multi-Modal Industrial Search
Pailitao Team (Core contributor)
[Paper]
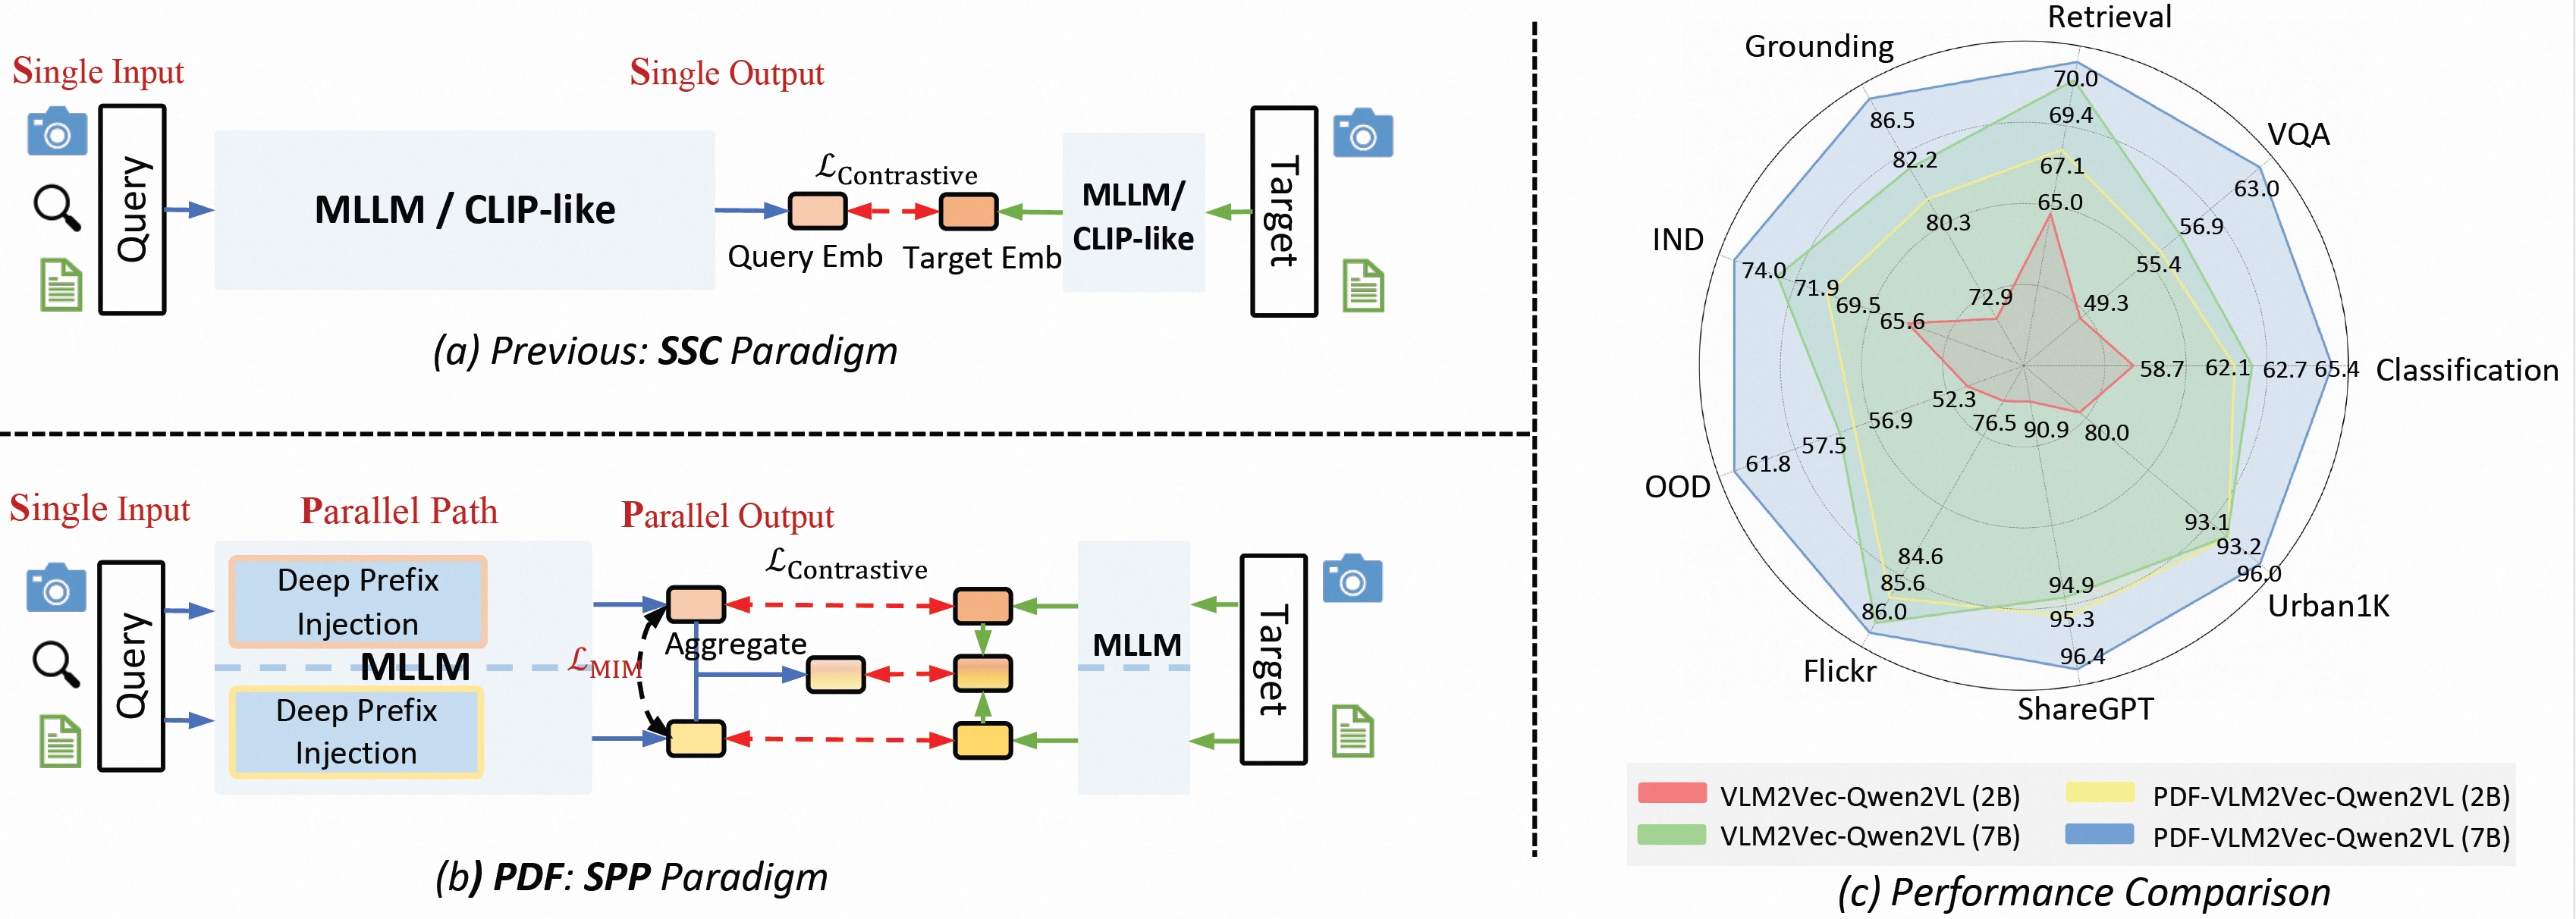
Arxiv 25.11 Explore More, Learn Better: Parallel MLLM Embeddings under Mutual Information Minimization
Zhicheng Wang, Chen Ju, Xu Chen, Shuai Xiao, Jinsong Lan, Xiaoyong Zhu, Zhiguo Cao
[Paper]
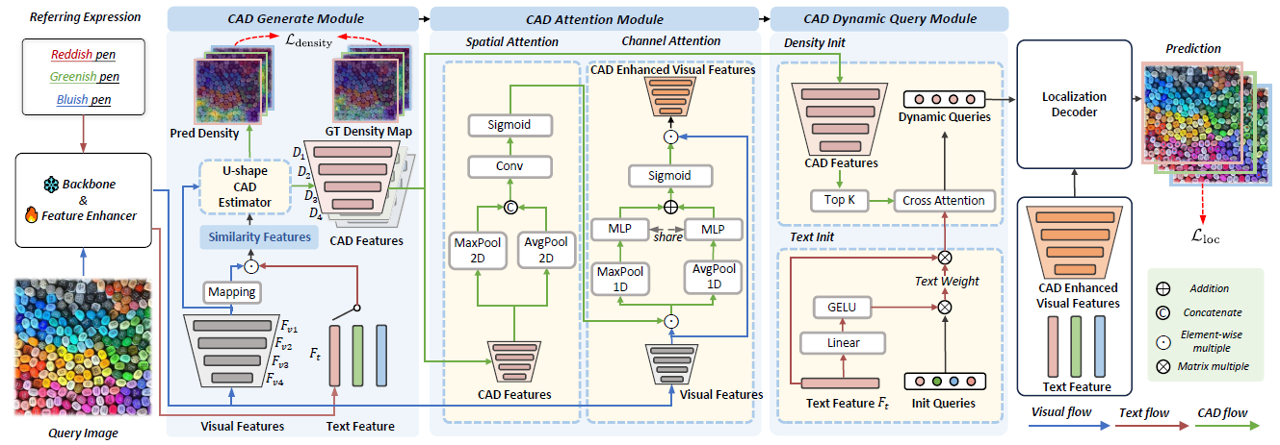
CVPR 2025 Exploring Semantic Density for Referring Expression Counting
Zhicheng Wang, Zhiyu Pan, Liwen Xiao, Zhan Peng, Jian Cheng, Wei Jiang, Shuaiyuan Du, Zhiguo Cao
[Paper]
[Code]
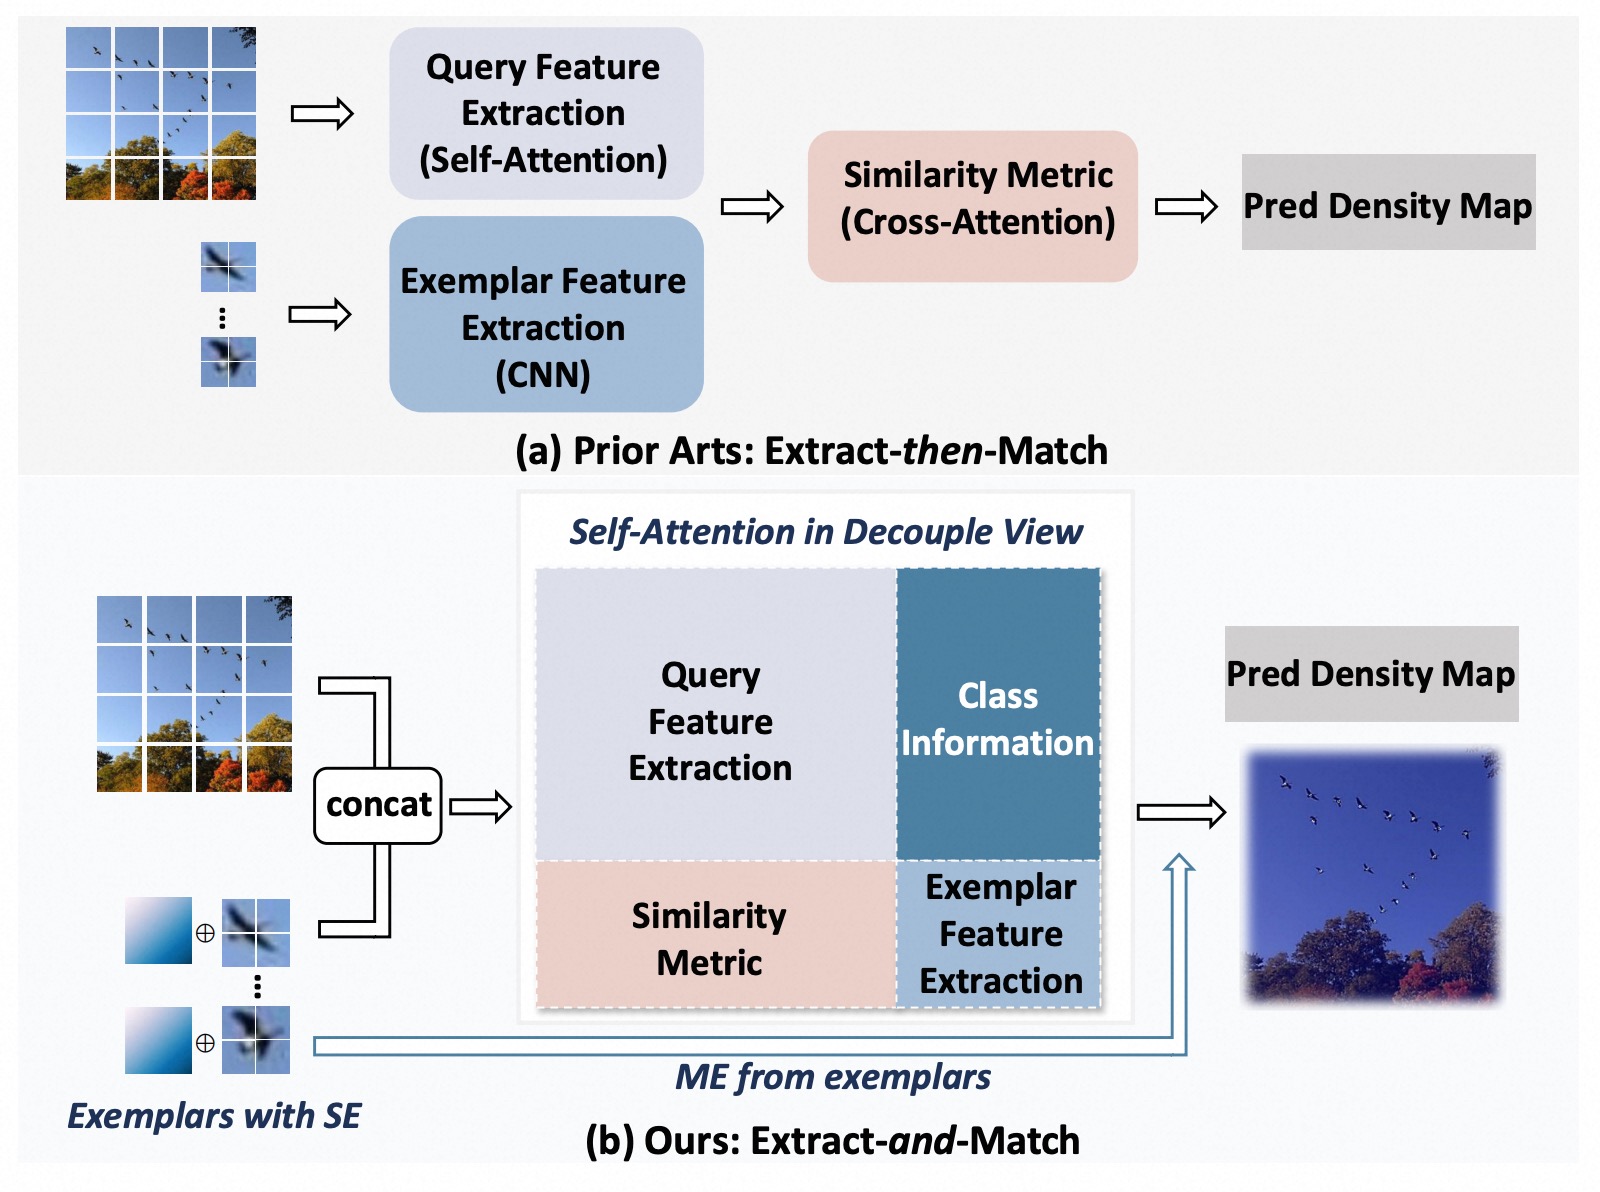
AAAI 2024 Vision Transformer Off-the-Shelf: A Surprising Baseline for Few-Shot Class-Agnostic Counting
Zhicheng Wang, Liwen Xiao, Zhiguo Cao, Hao Lu
[Paper]
[Code]
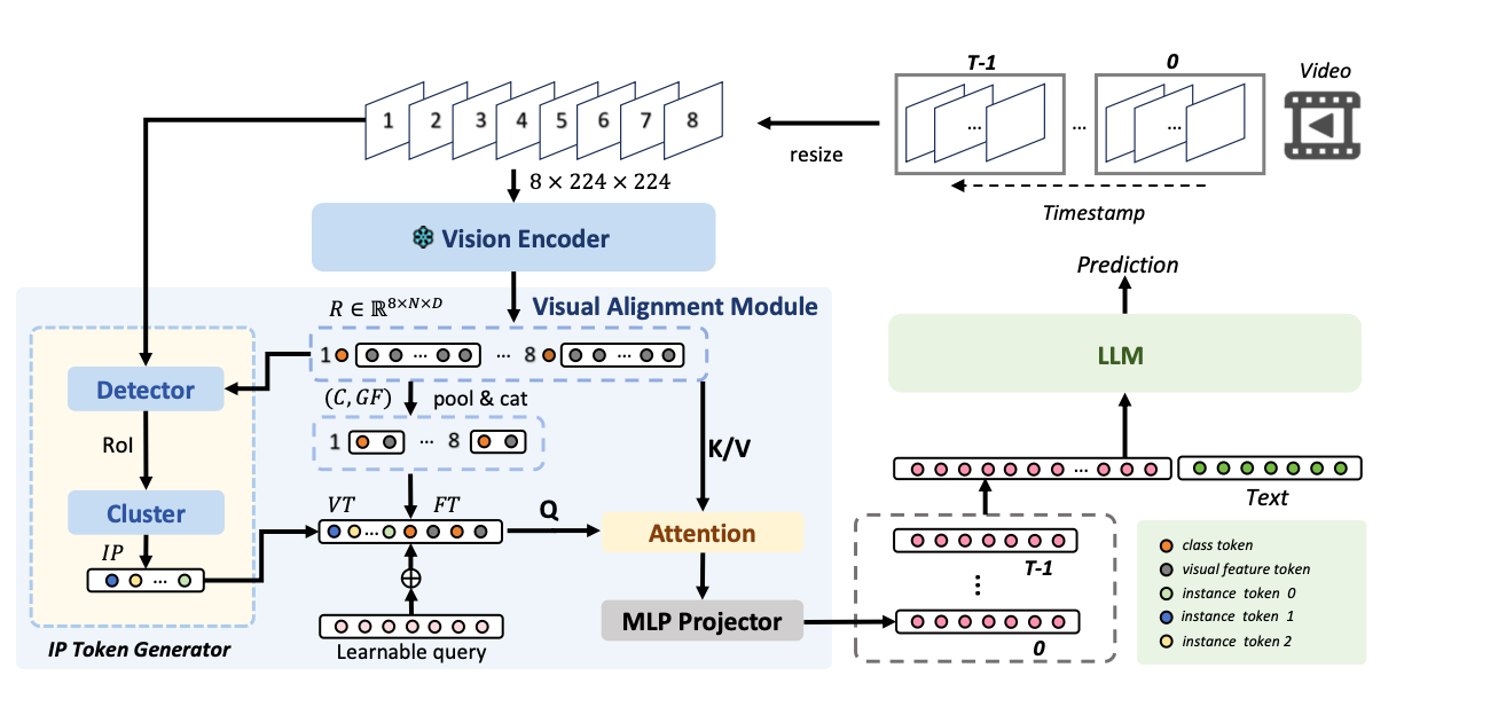
AAAI 2026 IPFormer-VideoLLM: Enhancing Multi-modal Video Understanding for Multi-shot Scenes
Yujia Liang, Jile Jiao, Xuetao Feng, Zixuan Ye, Yuan Wang, Zhicheng Wang*
[Paper]
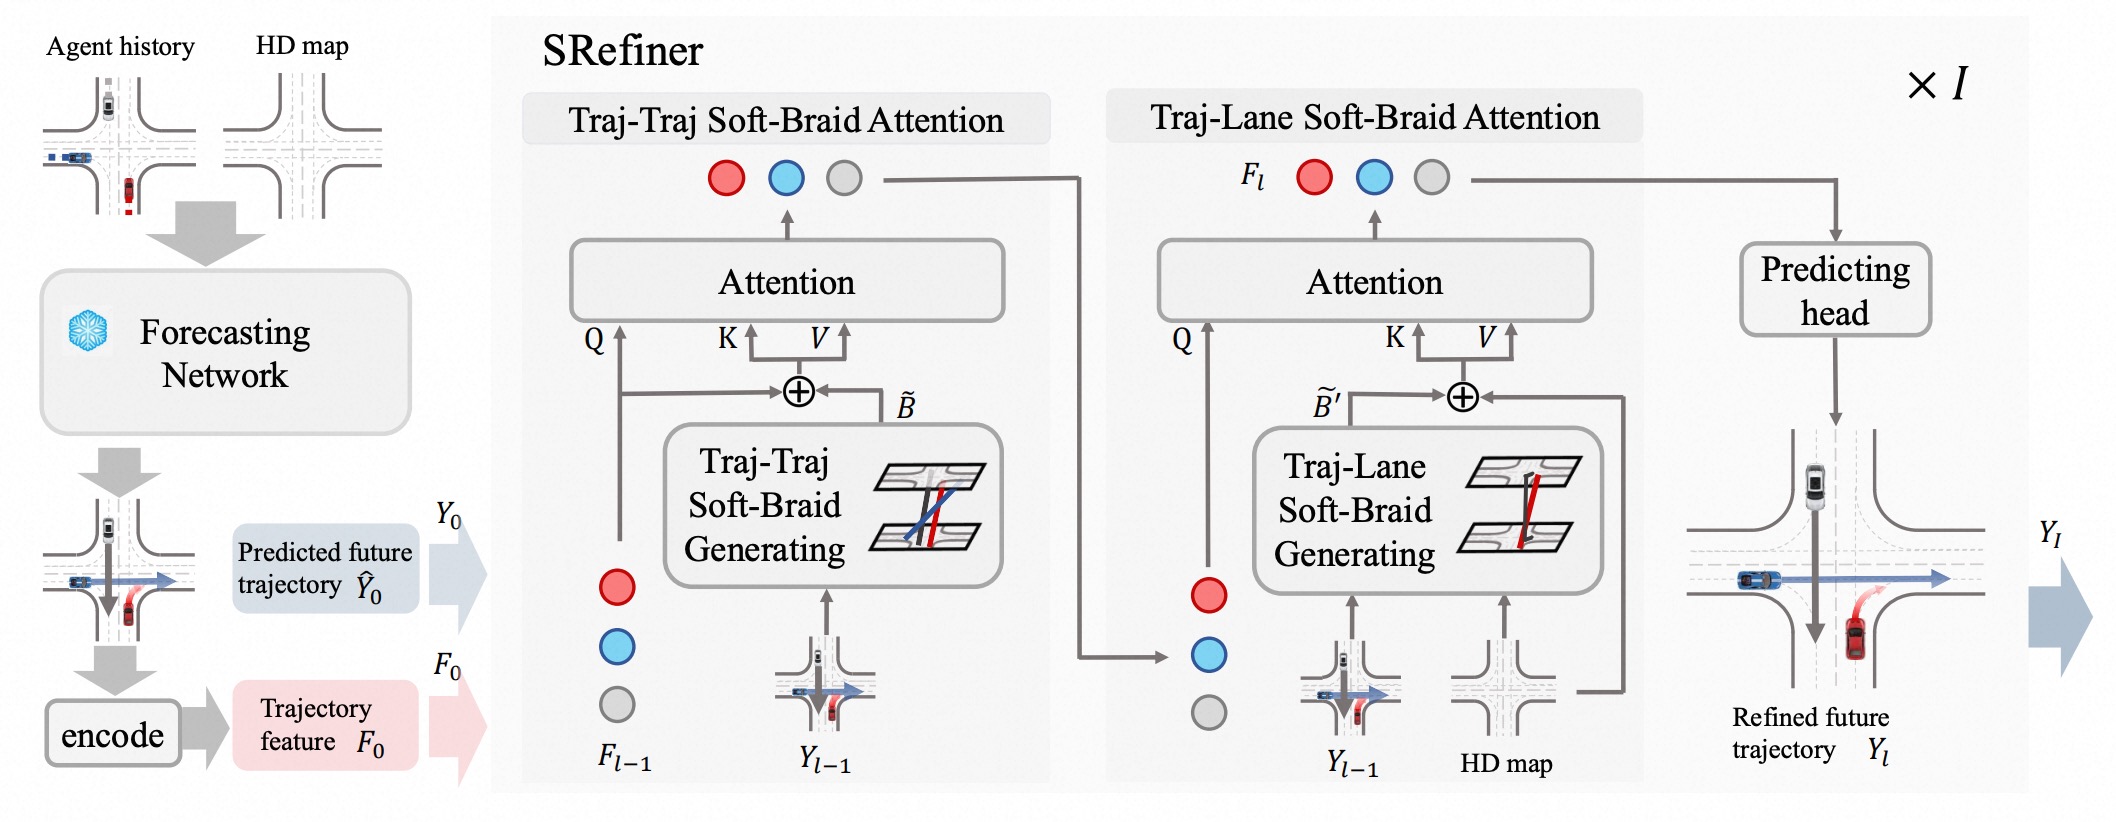
ICCV 2025 Highlight SRefiner: Soft-Braid Attention for Multi-Agent Trajectory Refinement
Liwen Xiao, Zhiyu Pan, Zhicheng Wang, Zhiguo Cao, Wei Li
[Paper]
[Code]
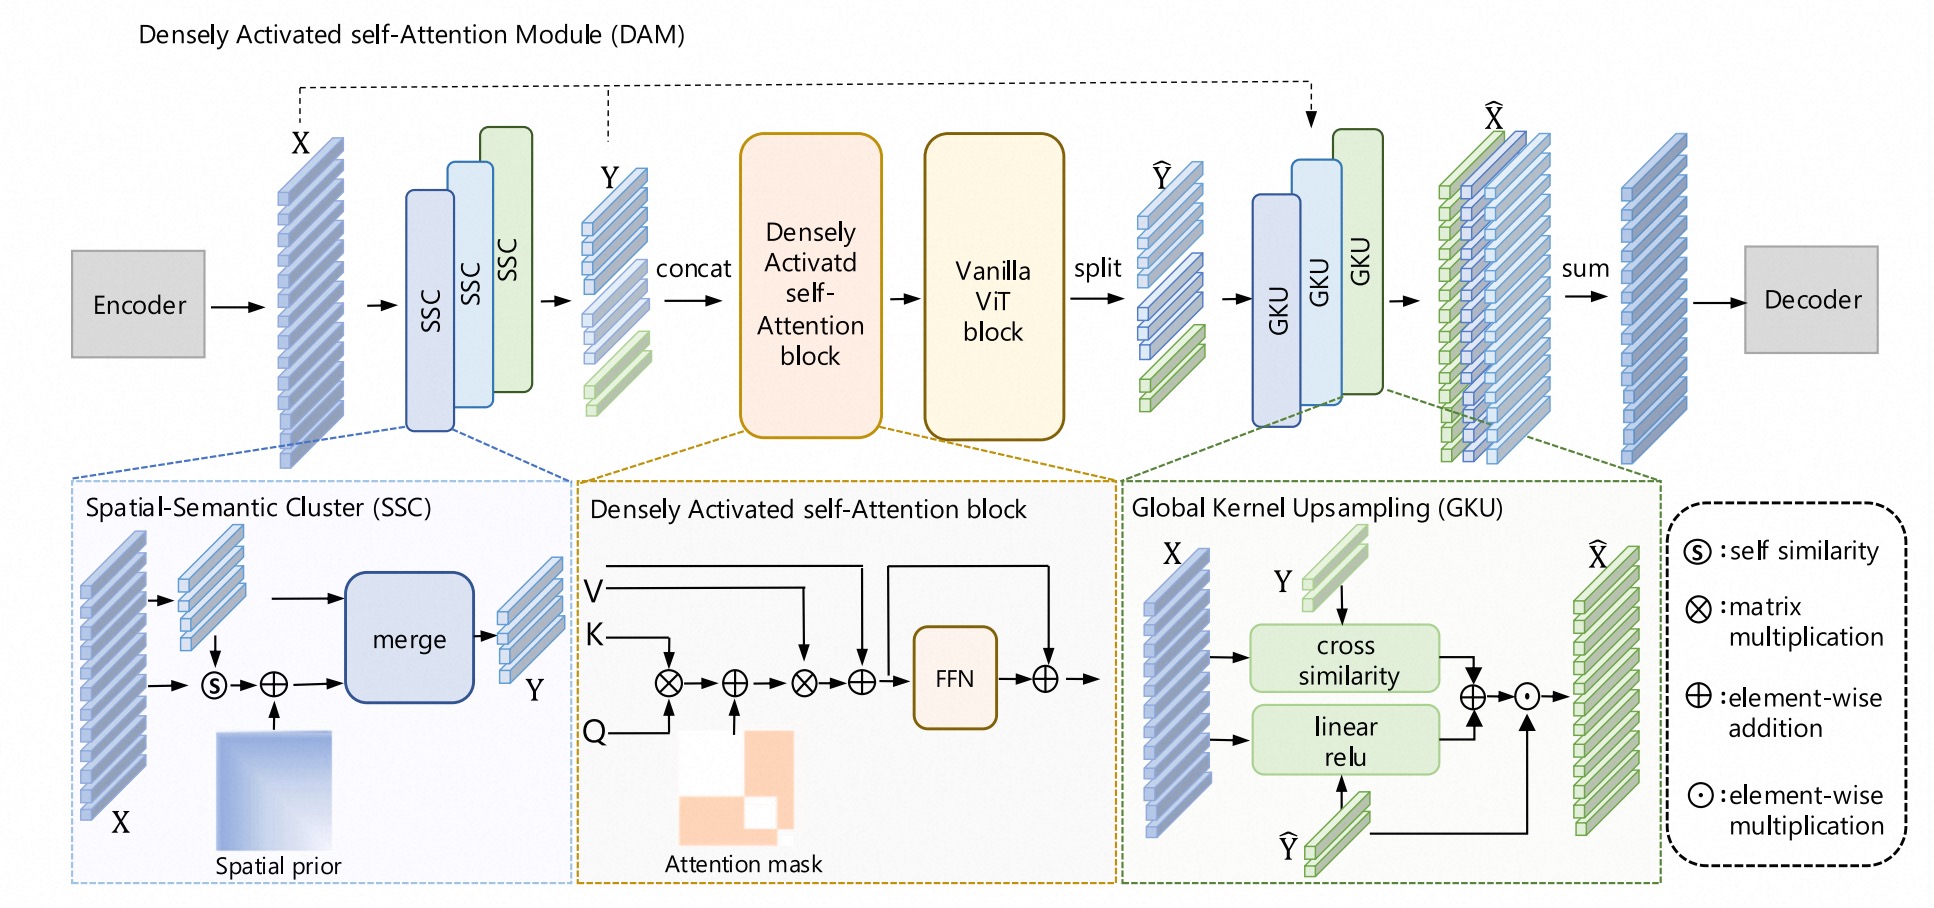
PR Densely Activated Self-Attention for Semantic Segmentation
Liwen Xiao, Wenze Liu, Zhicheng Wang, Zhiyu Pan, Yiran Wang, Zhiguo Cao, Hao Lu
[Paper]
Honors and Awards
- 2026 Top Talent Program by Technology Companies (Ant Group AntStar Talent Program)
- 2025 National Scholarship (Top 0.2% Nationwide)
- 2024 The Lead Intelligent and Wang Yanqing Scholarship (先导智能·王燕清奖学金),
- 2024 Weichai Power Scholarship (“潍柴动力”奖学金)
- 2023 Outstanding graduates
- 2021 Merit Student
- 2020 Outstanding Undergraduate Student (Top 1%)
Internships
- 2026.03 - 2026.06, ByteDance, Data, Search Multimodal Team.
- 2025.02 - 2025.12, Alibaba, Future Living Lab, Pailitao(拍立淘).
- 2024.07 - 2024.12, Shanghai AI Lab.
- 2024.06 - 2025.02, Worked on project “Camera Image Fusion and Reconstruction” with Huawei.